Seeing Culture: A Benchmark for Visual Reasoning and Grounding
Published in EMNLP 2025 (Main Conference), 2025
Burak Satar, Zhixin Ma, Patrick Amadeus Irawan, Wilfried Ariel Mulyawan, Jing Jiang, Ee-Peng Lim, Chong-Wah Ngo
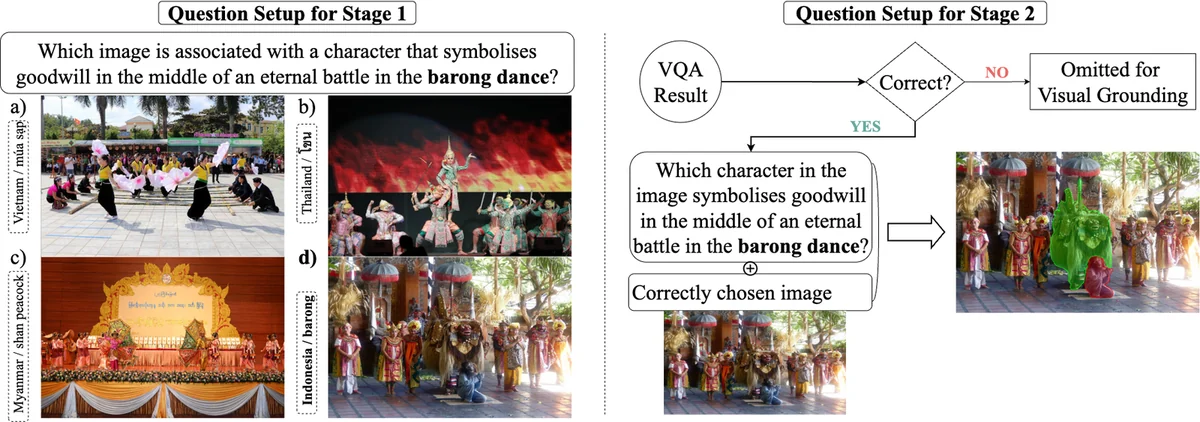
A two-stage benchmark where models must first reason about a cultural artifact, then visually ground it, built across Southeast Asia.
Paper (ACL)arXivProject siteCodeDataset
Key findings
- 1,065 images of 138 cultural artifacts from seven Southeast Asia countries, with 3,178 questions.
- Answering and grounding come apart. GPT-o3 answers 91% of across-culture questions correctly, yet its grounding never rises above 32.5 mean IoU: it names the right artifact while pointing at the wrong part of the image.
- Because every question is paired with a segmentation mask, a model that answers correctly for the wrong visual reason is caught. A single accuracy number cannot separate understanding from a lucky guess.
- The gaps are systematic rather than noise, and they are largest on questions that cross from one Southeast Asia culture to another.
What it covers
3,178 questions on 134 cultural artifacts across 7 countries, counted from the public question set of the Seeing Culture benchmark. The paper reports 138 artifacts in total; a few do not appear in the released questions.
- Indonesia1,377 questions · 35 artifacts
- Myanmar717 questions · 45 artifacts
- Thailand344 questions · 26 artifacts
- Vietnam324 questions · 11 artifacts
- Philippines212 questions · 10 artifacts
- Malaysia182 questions · 5 artifacts
- Cambodia22 questions · 2 artifacts
Browse the 1,065 images and 3,178 questions in the dataset viewer on Hugging Face.
Related
The video sequel, Cultural Moment (EMNLP 2026, oral), carries the visual-option design into video and adds free-form temporal localization: name the concept, recognize it among unlabeled video moments, then locate its sub-events in time. Its project page has a playable sample of all three stages.
BibTeX
@inproceedings{satar-etal-2025-seeing,
    title = "Seeing Culture: A Benchmark for Visual Reasoning and Grounding",
    author = "Satar, Burak  and
      Ma, Zhixin  and
      Irawan, Patrick Amadeus  and
      Mulyawan, Wilfried Ariel  and
      Jiang, Jing  and
      Lim, Ee-Peng  and
      Ngo, Chong-Wah",
    editor = "Christodoulopoulos, Christos  and
      Chakraborty, Tanmoy  and
      Rose, Carolyn  and
      Peng, Violet",
    booktitle = "Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing",
    month = nov,
    year = "2025",
    address = "Suzhou, China",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2025.emnlp-main.1131/",
    doi = "10.18653/v1/2025.emnlp-main.1131",
    pages = "22227--22243",
    ISBN = "979-8-89176-332-6"
}