Cultural Moment Benchmark: Evaluating Video Cultural Reasoning and Grounding in Southeast Asia
Published in EMNLP 2026 (Main Conference, oral), 2026
Burak Satar, Zhixin Ma, Cheng Yu-Tong, Huy Hoang Tran, Phuong Anh Nguyen, Chong-Wah Ngo
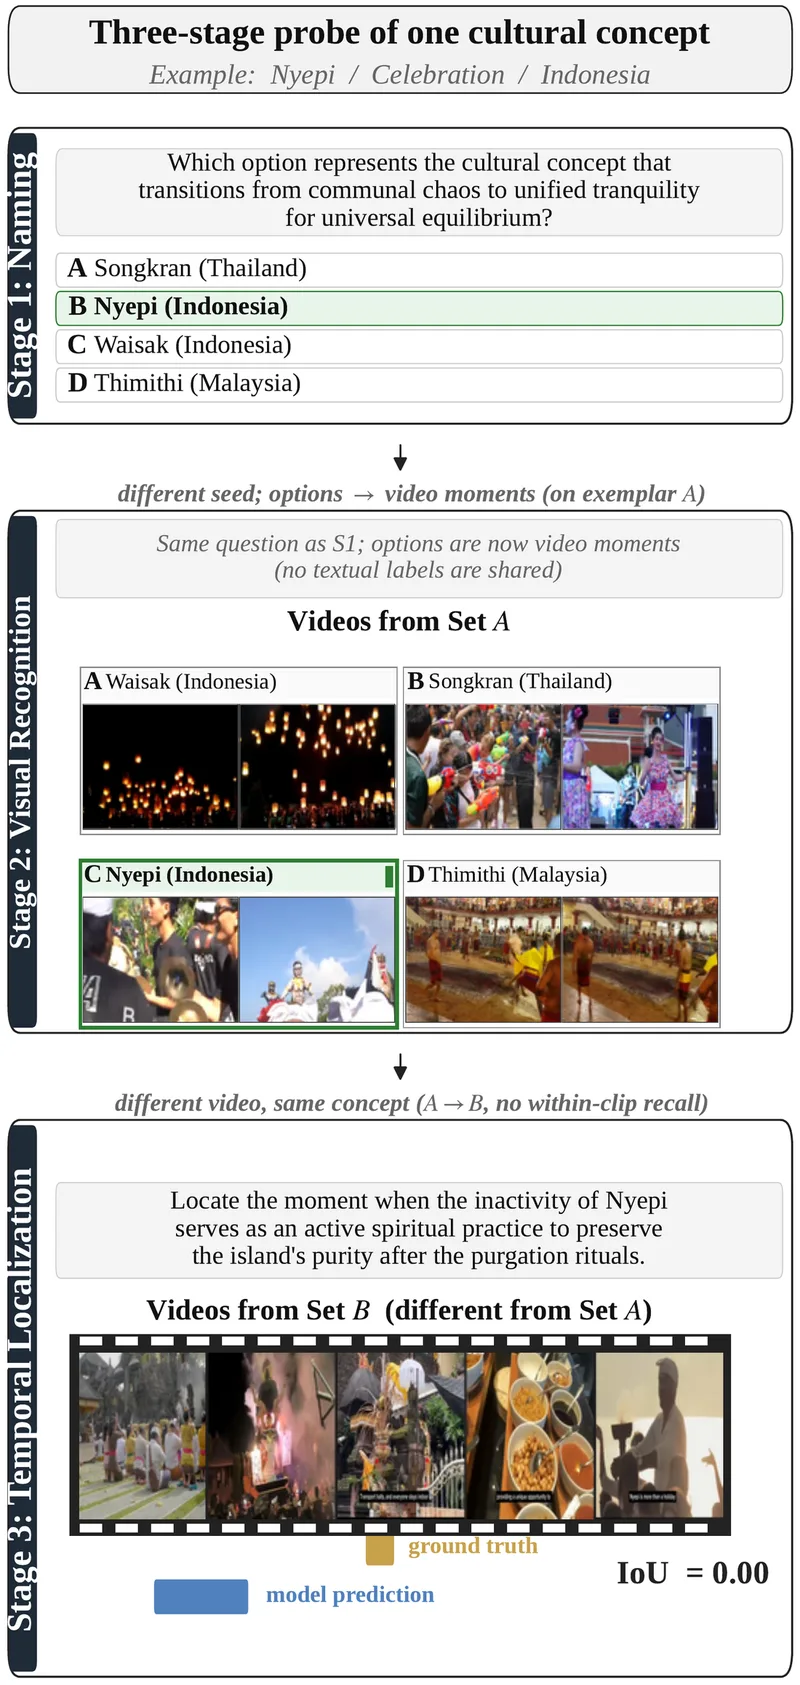
Three-stage video probes of cultural understanding across Southeast Asia: naming a concept, recognizing it among unlabeled video moments, and locating its sub-events in time.
Key findings
- 306 expert-curated cultural concepts from seven Southeast Asia countries across five categories, evaluated over 624 videos in a 3-stage by 3-mode framework.
- Cultural understanding is scored as three separate abilities, naming, recognition and temporal localization, and they do not compose: even the strongest closed-source models clear all three stages for fewer than 30% of concepts.
- A 14-rater human study shows the knowledge required is country-specific, not regional. A rater from one Southeast Asia country is not a proxy for the region.
- Accepted at the EMNLP 2026 Main Conference (15.4% acceptance rate) and selected for an oral presentation (2.7% acceptance rate).
What it covers
306 expert-curated concepts from seven Southeast Asian countries across five categories, evaluated over 624 videos in a 3-stage × 3-mode framework. Cultural understanding is scored as three separate abilities rather than one number, and the abilities do not compose: even the strongest closed-source models clear all three stages for fewer than 30% of concepts, and a 14-rater human study shows the knowledge required is country-specific, not regional.
Try the interactive walkthrough on the project page, where the leaderboard and challenge details also live. The paper is an oral at the EMNLP 2026 Main Conference (2.7% acceptance rate); the ACL Anthology version will be linked here once published.
Related
It builds on Seeing Culture (EMNLP 2025), which asks the same two-stage question, reason about a cultural artifact then ground it in the image, of still images rather than video. Cultural Moment carries the visual-option design into video and adds free-form temporal localization.
BibTeX
@misc{satar2026cultural,
    title={Cultural Moment Benchmark: Evaluating Video Cultural Reasoning and Grounding in Southeast Asia},
    author={Burak Satar and Zhixin Ma and Yu-Tong Cheng and Huy Hoang Tran and Phuong Anh Nguyen and Chong-Wah Ngo},
    year={2026},
    eprint={2608.23065},
    archivePrefix={arXiv},
    url={https://arxiv.org/abs/2608.23065}
}